You set a threshold alert on a checkout endpoint at 500ms. It pages you every Monday at 9am, when traffic doubles and nothing is actually wrong. You raise the threshold to 800ms to make the noise stop. Three weeks later a real regression creeps in at 650ms, and nobody gets paged, because you tuned the alert to survive Mondays instead of to catch problems.
This is the tradeoff with threshold-based alerts: set them tight and get paged for normal behavior, or set them loose and miss the thing you actually care about. We hear some version of “can you just tell us when something’s actually wrong?” constantly in support. It’s a reasonable thing to want and a hard thing to do with a single number.
Anomaly Detection skips the threshold entirely. It’s out of beta and available on every Scout plan, including free.
Scout Anomaly Detection automatically learns the normal performance of each endpoint and background job, then alerts you when response time meaningfully deviates from that baseline. It’s application performance anomaly detection built to run without any manual tuning up front.
How it works
Anomaly Detection is opt-in per endpoint and per background job. For each one you enable, Scout tracks average and 95th percentile response time (average only for background jobs) and compares the latest value against that endpoint’s own recent behavior every minute. A steady 100ms API route and a jittery search endpoint have different normal swings, so Scout measures each deviation relative to the endpoint’s own typical variability, not a number you picked once and forgot about.
A single sensitivity setting controls how big a deviation has to be before Scout flags it. Higher sensitivity catches smaller deviations and produces more events; lower sensitivity only catches large, obvious spikes.
And Mondays are handled. Before flagging a spike, Scout checks the same time 24 hours ago and the same time one week ago. If either window shows the current value would have looked normal, the spike gets treated as part of the endpoint’s usual rhythm and suppressed automatically. New endpoints get a bit more noise during their first week while the seasonal model warms up, then recurring patterns go quiet on their own.
What happens when something fires
When Scout catches the first anomalous minute that survives the seasonal check, it opens an event and, if you’ve set up a notification group, sends one notification. That’s it, one notification. While the anomaly stays active, Scout keeps updating the event with its peak value (the worst minute seen so far) but doesn’t page you again. No alert storms while you’re already looking at the problem.
The event closes on its own once the metric is back in its normal range for 3 consecutive minutes. If the endpoint goes quiet for 10+ minutes with no traffic, Scout closes any open events for it automatically rather than leaving a stale anomaly sitting open. Closed anomalies stay in your Insights History so you can go back and scan what happened last week without digging through raw charts.
Tuning sensitivity with a live preview
When you enable a monitor, Scout immediately backfills the past week of history so you can see what it would have caught before waiting for the next incident. That backfill also powers a live preview when you adjust sensitivity: drag the slider and the chart filters in real time, showing exactly how many past events each level would have produced.
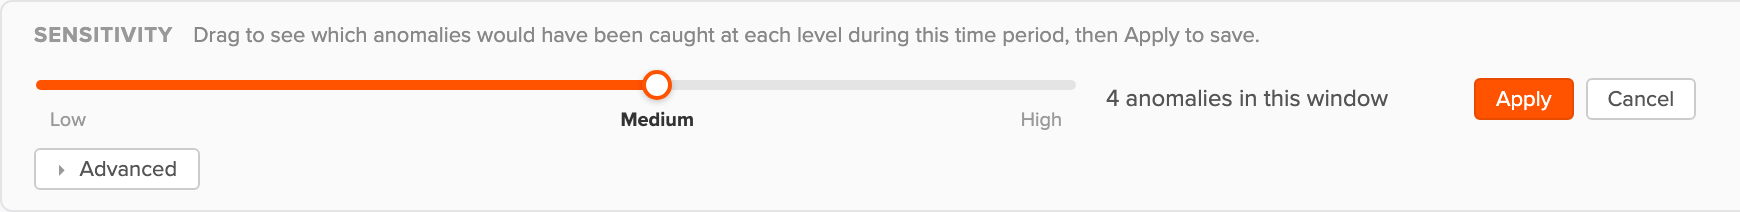
Nothing saves until you click Apply. Two advanced controls, minimum duration and direction (spikes, dips, or both), let you narrow detection further for specific endpoints and are saved alongside sensitivity.
Where anomalies show up
Once enabled, anomalies appear in the Insights tab with the metric, how far it drifted from baseline, and how long it lasted. An overlay toggle on your app’s Overview chart shows anomaly markers across all your monitored endpoints and jobs at once, and the same toggle on an individual endpoint or job shows shaded bands directly on its performance chart. Past anomalies also show up in Insights History alongside N+1, memory bloat, and slow query findings, and notifications fire through your existing Slack, PagerDuty, Opsgenie, email, or webhook channels when a new anomaly opens.
They’re also queryable from your AI coding agent. Scout’s MCP server includes tools for listing and inspecting anomaly events, so Claude Code, Cursor, or whatever you’re using can check which endpoints are behaving abnormally without you opening a dashboard.
Anomaly Detection isn’t the right tool for every endpoint. It needs steady traffic to build a baseline. Below roughly 10 requests per hour, there’s not enough data for it to say anything meaningful, and endpoints with wild minute-to-minute swings (some queries at 50ms, others at 5s) will look “always anomalous” to a statistical detector no matter how you tune it. For either of those, or for throughput dips and error spikes (which Anomaly Detection doesn’t cover yet), stick with threshold alerting. Use both where it makes sense. They’re solving different problems.
Who should turn this on
You don’t need it everywhere. It’s most useful on:
Endpoints where you don’t know what “normal” looks like. A reporting endpoint that gets slower as customer data grows, a search endpoint whose latency depends on what people are searching for. You could guess at a threshold, or you could let Scout learn the actual pattern.
Background jobs that only misbehave under load you can’t predict. A nightly export job is easy to threshold. A job triggered by user activity that scales unevenly with traffic isn’t.
Endpoints you already treat as important, but haven’t gotten around to alerting on. Setting up a good threshold takes time and a few false starts. Anomaly Detection’s week-long backfill means you can turn it on and immediately see whether it would have caught your last few incidents, no tuning required to get useful signal on day one.
Enabling it
Anomaly Detection is included on every plan. Free gets 1 monitor, paid plans get 10, and you can add more for $10/month. Turn it on from the Monitoring dropdown on any endpoint or background job’s detail page.
The question worth asking isn’t “what threshold should I set?” It’s “would I actually notice if this endpoint quietly got worse?” If the answer is no, that’s the endpoint to enable this on first.
Questions about tuning it for your setup? Reach out at support@scoutapm.com. New to Scout? Get a demo with a solutions engineer.
For application monitoring with errors, logs, and traces, Scout Monitoring provides the fastest insights without the bloat.